⚡ Understanding the Thundering Herd Problem in Distributed Systems

Introduction: A Simple Real-World Analogy
Before e-commerce became mainstream, people would queue outside stores during special sales like Black Friday. The moment the doors opened, everyone rushed in at the same time. The store suddenly became overcrowded. Staff were overwhelmed, checkout lines grew longer, and the shopping experience deteriorated.
A similar phenomenon happens in software systems.
When a large number of clients attempt to access the same resource simultaneously, the system can become overloaded. This phenomenon is known as the Thundering Herd Problem.
In this article, we’ll explore:
What the thundering herd problem is
Where it commonly appears in distributed systems
Why it becomes dangerous at scale
Techniques used to mitigate it
Trade-offs of those techniques
What engineers (especially SDETs) can test to detect it early
What Is the Thundering Herd Problem?
The Thundering Herd Problem occurs when multiple clients simultaneously send requests to a shared resource, causing performance degradation or even system failure.
In simple terms:
Many users need the same data
Requests arrive at the same time
The cache cannot absorb the load
The backend system becomes overwhelmed
This synchronized surge of requests is called a herd.
Where Does This Problem Commonly Occur?
The thundering herd problem frequently appears in systems that rely on shared resources such as:
Caching layers
Databases
Authentication services
Load balancers
Configuration services
It is especially common in cache-heavy architectures.
A Typical System Architecture
Most modern systems follow a layered architecture like this:
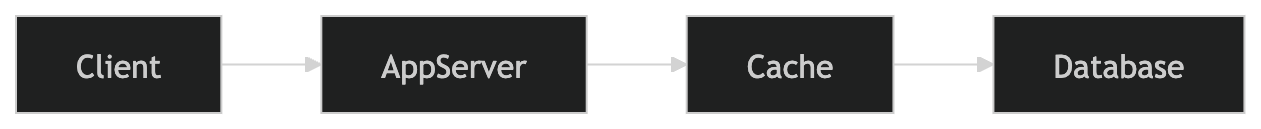
Normal Behavior
Client sends a request
Server checks the cache
Cache returns the data
Database is rarely accessed
This results in:
Low latency
Reduced backend load
High system efficiency
Real-World Scenario: Cache Expiry
Normal Flow
When the cache is valid: Users → Cache (Hit) → Fast Response
Everything works smoothly. The database remains mostly idle.
What Happens When Cache Expires?
Cache entries usually have a TTL (Time To Live).
When TTL expires:
Cache entry disappears
Thousands of clients request the same data
Cache returns a miss
All requests hit the database
Database becomes overloaded
Users → Cache (Miss) → Database (Overload)
This synchronized burst of requests creates the thundering herd.
Normal Traffic Spike vs Thundering Herd
| Normal Spike | Thundering Herd |
|---|---|
| Gradual traffic increase | Sudden synchronized burst |
| System can adapt | System becomes overwhelmed |
| Cache still helps | Cache becomes ineffective |
The key difference is synchronization.
Why It Is Dangerous in Distributed Systems
Modern systems consist of multiple dependent services.
When one service slows down:
Threads get blocked
Request queues grow
Retries increase
Failures propagate
This creates a cascade effect where a small issue can escalate into a large outage.
Impact on System Performance
CPU
High context switching
Thread starvation
Increased CPU utilization
Database
Connection pool exhaustion
Slow queries
Timeout errors
Cache
High miss rates
Reduced effectiveness
Repeated backend calls
Latency
Increased response time
User-visible delays
Higher error rates
Timeline View of the Problem
Without Protection
10:00 → Cache expires
10:01 → 10k requests
10:02 → DB overload
10:03 → Service degradation
With Protection
10:00 → Cache expires
10:01 → Single refresh
10:02 → Cache refilled
10:03 → Normal traffic
Techniques to Prevent the Thundering Herd
In practice, no single solution is sufficient. Systems usually combine multiple techniques.
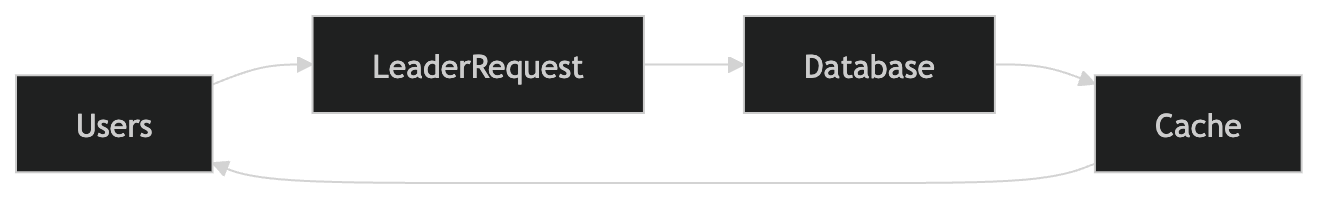
1. Request Coalescing
Concept
Multiple identical requests are merged into a single backend request.
Trade-offs
| Benefit | Trade-off |
|---|---|
| Reduces DB load | Higher waiting latency |
| Avoids duplication | Bottleneck risk |
| Efficient refresh | Complex logic |
If the leader request fails, all dependent requests are affected.
What to Test
Fire 1000 parallel requests for same key
Verify single DB call
Kill leader request mid-way
Check recovery behavior
🚩 Red Flag: Requests hang indefinitely.
2. Cache Locking / Mutex
Concept
Only one instance refreshes the cache using a lock.

Trade-offs
| Benefit | Trade-off |
|---|---|
| Strong consistency | Deadlock risk |
| Controlled refresh | Reduced throughput |
| Backend protection | Lock overhead |
What to Test
Acquire lock and refresh
Crash lock-holder
Verify lock timeout
Test failover behavior
🚩 Red Flag: Infinite waiting.
3. Staggered Expiry (Randomized TTL)
Concept
Cache entries expire at different times.
Expiry Window: 9:55 – 10:05
Trade-offs
| Benefit | Trade-off |
|---|---|
| Smooth load | Stale data |
| Simple | Partial protection |
| Low cost | Debug difficulty |
What to Test
Monitor expiry distribution
Validate freshness
Check clustering patterns
🚩 Red Flag: Mass simultaneous expiry.
4. Exponential Backoff
Concept
Clients progressively increase retry intervals.
5s → 30s → 1m → 2m ...
Trade-offs
| Benefit | Trade-off |
|---|---|
| Prevents retry storms | Slow recovery |
| Reduces pressure | UX impact |
| Stabilizes system | Needs tuning |
What to Test
Simulate failures
Track retry intervals
Enforce retry limits
🚩 Red Flag: Aggressive retries.
5. Rate Limiting
Concept
Restrict the number of requests per user, IP, or service.
Trade-offs
| Benefit | Trade-off |
|---|---|
| Backend protection | Legit user blocking |
| Abuse prevention | Threshold tuning |
| Stable performance | Monitoring cost |
What to Test
Exceed limits
Validate 429 responses
Test whitelist/bypass rules
🚩 Red Flag: Backend overload despite limits.
Learning Note
This article reflects my current understanding of the thundering herd problem. Topics such as distributed locking algorithms, leader election, and adaptive caching strategies go deeper into distributed system design and are worth exploring further.
Feedback and suggestions are always welcome.
Conclusion
The Thundering Herd Problem occurs when large numbers of synchronized requests overwhelm shared resources.
Key takeaways:
It commonly occurs in cache-heavy architectures
It can trigger cascading failures in distributed systems
It impacts CPU, databases, caches, and latency
Effective mitigation requires layered protection strategies
Understanding system behavior, mitigation trade-offs, and testing approaches helps engineers design more resilient and scalable systems.
Thank you for your time. :)

